The August datasets
Versions 1 to 5, all public on Hugging Face in the LeRobot format. Any episode opens in the browser with all its cameras, the joint trajectory and the prompt on one timeline. The October set is on the Data page.
The demonstrations behind the evaluated policy
150 teleoperated demonstrations, about 58 minutes of recording: a person drives the leader arm while the cameras, the joint positions and the prompt are logged at 30 frames a second. Each demonstration is one move.
The set is sari-abdan/vial-sort-v5 on Hugging Face, and every episode can be watched in the browser.
How the demonstrations were recorded
- Three vial colours, red, cyan and green, three vials of each.
- Two six-slot racks at a diagonal to the arm, the bin on the left.
- Places are named from the side camera: the left rack is the one by the bin, and slots run 1 to 6 from left to right.
- Vials are spaced so no two stand side by side, at most three to a rack; the other vials are never the colour being moved.
- Slots 2 and 5 are never a source, so the evaluation can test two positions no demonstration started from.
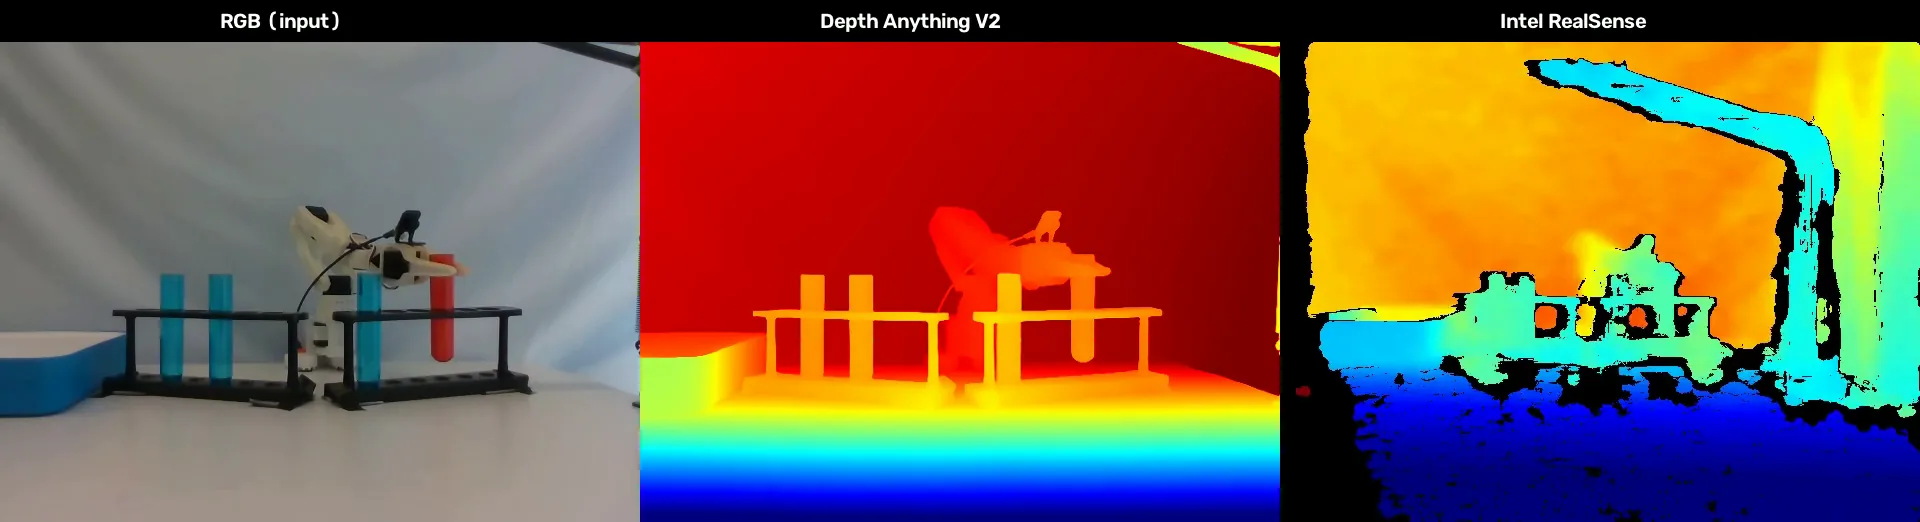
- The depth stream is recorded with every episode and not used by the policy.
Every demonstration has its own wording
150 wordings for 150 demonstrations, so the policy has to read the positions rather than memorise one sentence. The 8 for R1 → bin:
- “Bring the tube at hole 1 of the rack on the right into the trash can.”
- “Carry the test tube in position 1 of the right-side rack to the bin.”
- “Move the sample tube from slot 1 of the right tube rack over to the trash.”
- “Move the vial from position 1 of the right rack to the bin.”
- “Relocate the test tube from spot 1 of the right-side rack to the rubbish bin.”
- “Take the sample tube at the first slot of the right tube rack into the waste bin.”
- “Take the vial in slot 1 of the right rack to the trash.”
- “Transfer the tube from the first slot of the rack on the right over to the waste bin.”
Why the policy uses no depth
The vials are translucent plastic. The RealSense camera’s depth loses them; a model that estimates depth from the colour image alone keeps their shape. The policy is trained on the colour images.
Every dataset
Training datasets on the Hub
Each dot is one set of recordings; two names on a dot are the same recordings in two formats (joint and end-effector).
Show the numbers
| Dataset | Uploaded | Episodes | Minutes | Cameras | |
|---|---|---|---|---|---|
| vial-sort-v1-static | 7 Jun 2026 | 100 | 36 | cam_top, cam_wrist, cam_side | watch |
| vial-sort-v1-ee | 8 Jun 2026 | 100 | 36 | cam_top, cam_wrist, cam_side | watch |
| vial-sort-v2-static | 23 Jun 2026 | 120 | 40 | cam_top, cam_wrist, cam_side | watch |
| vial-sort-v4-new | 29 Jun 2026 | 40 | 12 | cam_top, cam_wrist, cam_side | watch |
| vial-sort-v5-pilot | 10 Aug 2026 | 150 | 58 | cam_top, cam_wrist, cam_side, cam_depth | watch |
| vial-sort-v5 | 22 Aug 2026 | 150 | 58 | cam_top, cam_wrist, cam_side, cam_depth | watch |
| vial-sort-slots-100 | 14 Oct 2026 | 100 | 33 | top_down, left_top, left_bottom, right, wrist | watch |
| vial-sort-contrast-51 | 10 Nov 2026 | 51 | 20 | top_down, left_top, left_bottom, right, wrist | watch |
| vial-sort-slots-220 | 10 Nov 2026 | 220 | 79 | top_down, left_top, left_bottom, right, wrist | watch |
| vial-sort-contrast-99-depth | 10 Nov 2026 | 99 | 34 | top_down, left_top, left_bottom, right, wrist, rs_depth | watch |